Live testing, real evidence. Delivered in 24 hours.
We run 50 real buyer questions across 6 AI tools and log every answer and source as evidence.
THE LOOP · HOW THE WORK SEQUENCES
From your website to a decision-ready audit in 24 hours.
01
Measure
We run the audit. You give us your website and your top competitors. We test it with 50 real buyer questions across 6 AI tools, crawl your whole site, and check whether AI can actually reach you. Every finding is backed by evidence.
02
Fix
A clear, ranked plan. We fix the biggest problems first: unblock AI crawlers, add the right schema, and build out your FAQ. Then we move to the core work. Every fix is ordered by how much it moves your score for the effort.
03
Produce
Content you can use today. You get ready-to-publish schema, rewritten headings tied to what buyers actually ask, a full FAQ section, and a fact sheet. Your team can start the same day.
04
Re-measure
We test again the same way. Monthly re-audits track real movement against your starting score. GEO is an ongoing program: measure, act, measure again.
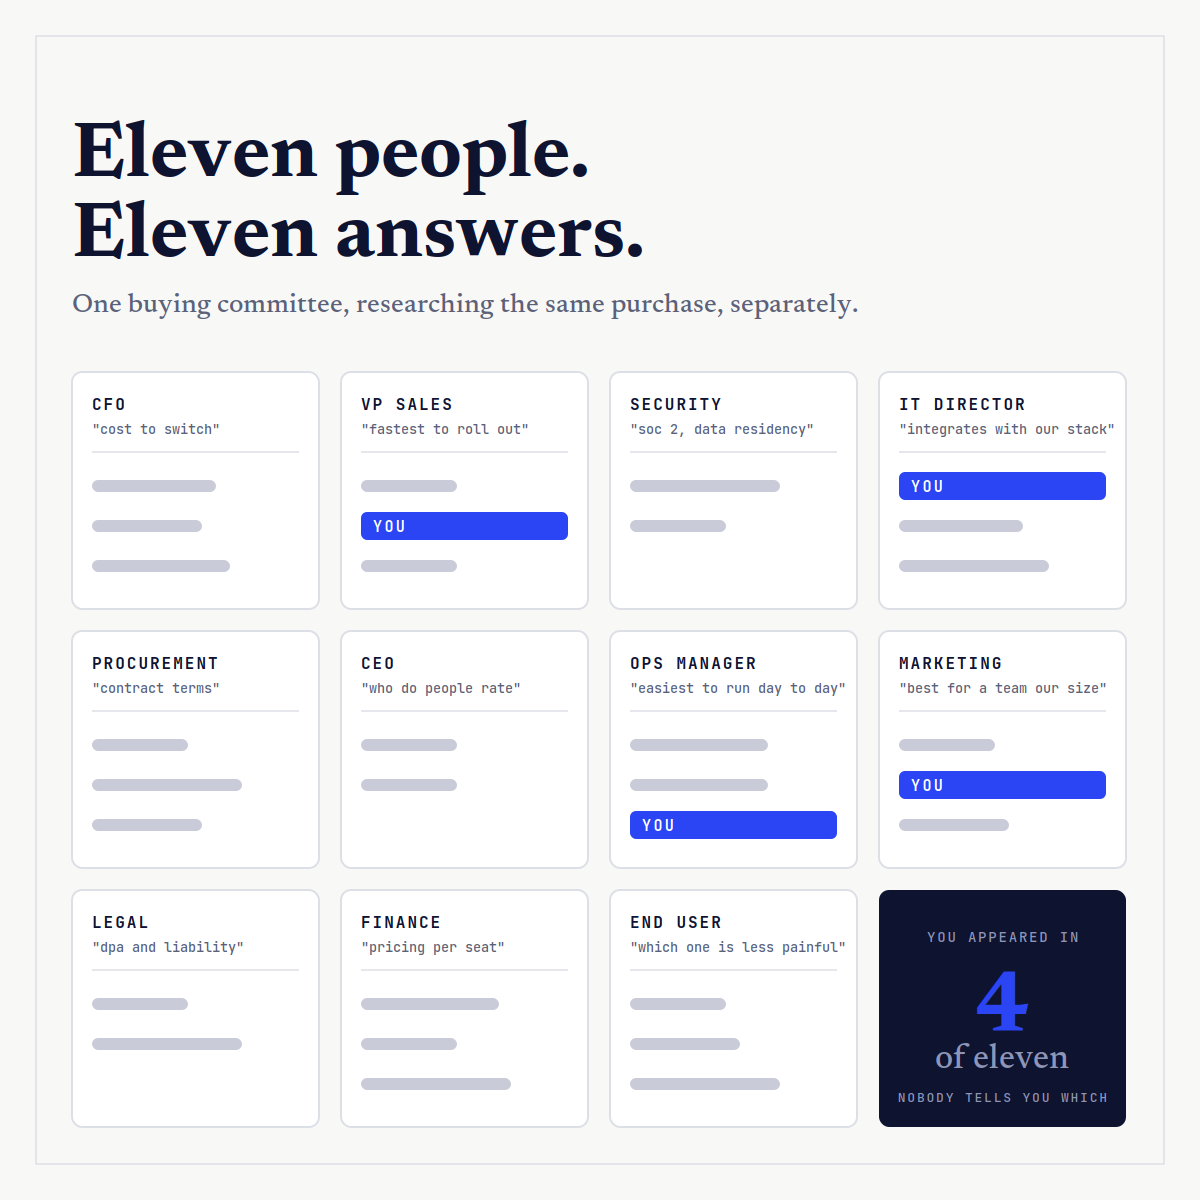
The buying committee
Eleven people. Eleven answers.
One buying committee, researching the same purchase, separately. Each person asks AI a different question — cost, security, integrations, who peers rate — and gets a different shortlist back.
You appeared in four of those eleven answers. Nobody tells you which four, or what the other seven people were even told. That is the gap VISIBLD measures and closes.
4
OF ELEVEN
NOBODY TELLS YOU WHICH
The 6 Buyer AI Platforms (with provenance)
"We test every platform" means little if half the answers are guessed.
The difference between a live answer and one from memory is itself a finding. A model answering from memory tells you about brand awareness built into training. A grounded model tells you whether AI can find you right now. We keep the two apart.
MEASURED · grounded
Grounded · Automated · Logged
We run your questions live and save the full answer text and every source URL. Each response is kept as evidence.
- → ChatGPT (OpenAI, web search)
- → Claude (Anthropic, web search)
- → Gemini (Google, search-grounded)
- → Perplexity (Sonar)
- → Grok (xAI, real-time web and X)
MEASURED · ungrounded
Training Memory Only · Flagged
Answers come from the model's training memory, not live web results. We report these but flag them clearly. This tells you about brand awareness built into training, which is a different question from live AI-search visibility.
- → DeepSeek
ASSISTED
Human-Assisted Capture
No public API exists. We capture these by hand with a clear, documented process (clean session, region noted, screenshot plus full text) and score them the same way. Until captured, they show as not tested, never a made-up mark.
- → Google AI Overviews
- → Microsoft Copilot
The 4-Stage Buyer-Journey Battery
One set of questions per stage. Run live, logged, and traceable.
Buyers describing the symptom, not the category. ("Why are my pipeline meetings dropping?") Shows whether AI even recognizes the problem your brand solves.
Buyers naming the category but not vendors. ("What's the best way to score pipeline intent?") Tests whether your brand enters the conversation at the category level.
Buyers comparing named alternatives. ("X vs. Y vs. Z for mid-market.") Shows your AI Share of Voice against named competitors and how AI frames each option.
Late-stage checks. ("Is [brand] legit? What do reviewers actually say?") Surfaces wrong info, sentiment, and the sources AI trusts to vouch for you.
The Audit Phases
Inside the audit: every phase, every signal
Calibration
You submit your website, your ideal customer, and up to 5 named competitors. We tune the buyer questions to your category and location and build the verified fact sheet that anchors the wrong-info check.
Live Prompt Battery
Every question runs live against ChatGPT, Claude, Gemini, Perplexity, and Grok. The answer text and exact source URLs are captured. Each question gets a pass, partial, or fail per platform, built only from real responses.
Ungrounded and Assisted Capture
DeepSeek is tested automatically and flagged as training memory only. Google AI Overviews and Copilot are captured by hand with a clear process (screenshot plus full text) and scored the same way.
Technical Teardown
A live technical audit: schema types and validity, meta and social tags, canonical, hreflang, robots.txt rules for 17 named AI crawlers, sitemap, llms.txt, HTTPS, status codes, and Core Web Vitals.
Content and Entity Inspection
Page inventory, FAQ detection, question-shaped heading ratio, the first 200 words of each page, and a list of thin pages. We also check your company entity graph, sameAs links, name-address-phone consistency, and real existence on Wikidata, Wikipedia, and the Google Knowledge Graph.
Citation Source and SOV
Which domains the models actually cite for your topic, how often they cite you, and the source mix. AI Share of Voice for you and every named competitor, computed from the same real responses.
Hallucination and Sentiment
Contradictions, unverified claims, made-up info, and brand-safety flags, checked against the verified fact sheet. Sentiment, framing (recommended, listed, or cautioned), and the themes AI attaches to your brand, drawn from the models' own words.
Fix Kit and 30/60/90 Roadmap
Ready-to-paste schema, rewritten headings page by page, a complete FAQ section, a complete llms.txt, an entity plan, ROI framing, and a step-by-step roadmap that says who does what, the effort, and the priority. PDF with evidence appendix.
THE LINE THE BRAND IS BUILT ON
Find out if AI sees your company, before your competitors do.
VISIBLD checks whether the AI tools your buyers use can find, trust, and recommend your company, shows you exactly what is keeping you out, and does the work to fix it.
Fixed fee · Delivered in 24 hours · Founded by Jordan Neville